
Bengaluru-based Gnani AI, a voice-AI startup that builds speech and enterprise AI systems, launched Artha on August 28 as an end-to-end AI stack for Indian enterprises and public institutions. The launch received unusually high-level government visibility: Vice President CP Radhakrishnan formally unveiled Artha at Uprashtrapati Bhavan in New Delhi.
In simple terms, sovereign AI means having greater control over the models, data and infrastructure an organisation depends on, rather than relying entirely on external systems. Artha is built around that idea. It combines Gnani’s Evon 3.3 language model with its Plexus agentic platform and is designed so organisations can run AI inside their own data centres or private cloud environments.
The launch adds another dimension to India’s sovereign-AI push. Model size still matters, but Artha raises a broader question: should India measure AI capability primarily by parameter counts, or by how much control institutions have over the models, data and infrastructure they use?
What Is Changing?
Evon 3.3 is a 30-billion-parameter open-weight model trained across English and 10 Indian languages, but only roughly 3.5 billion parameters are active for each token. In practical terms, that means the model can use less computing power while running, potentially lowering the cost for institutions that deploy it.
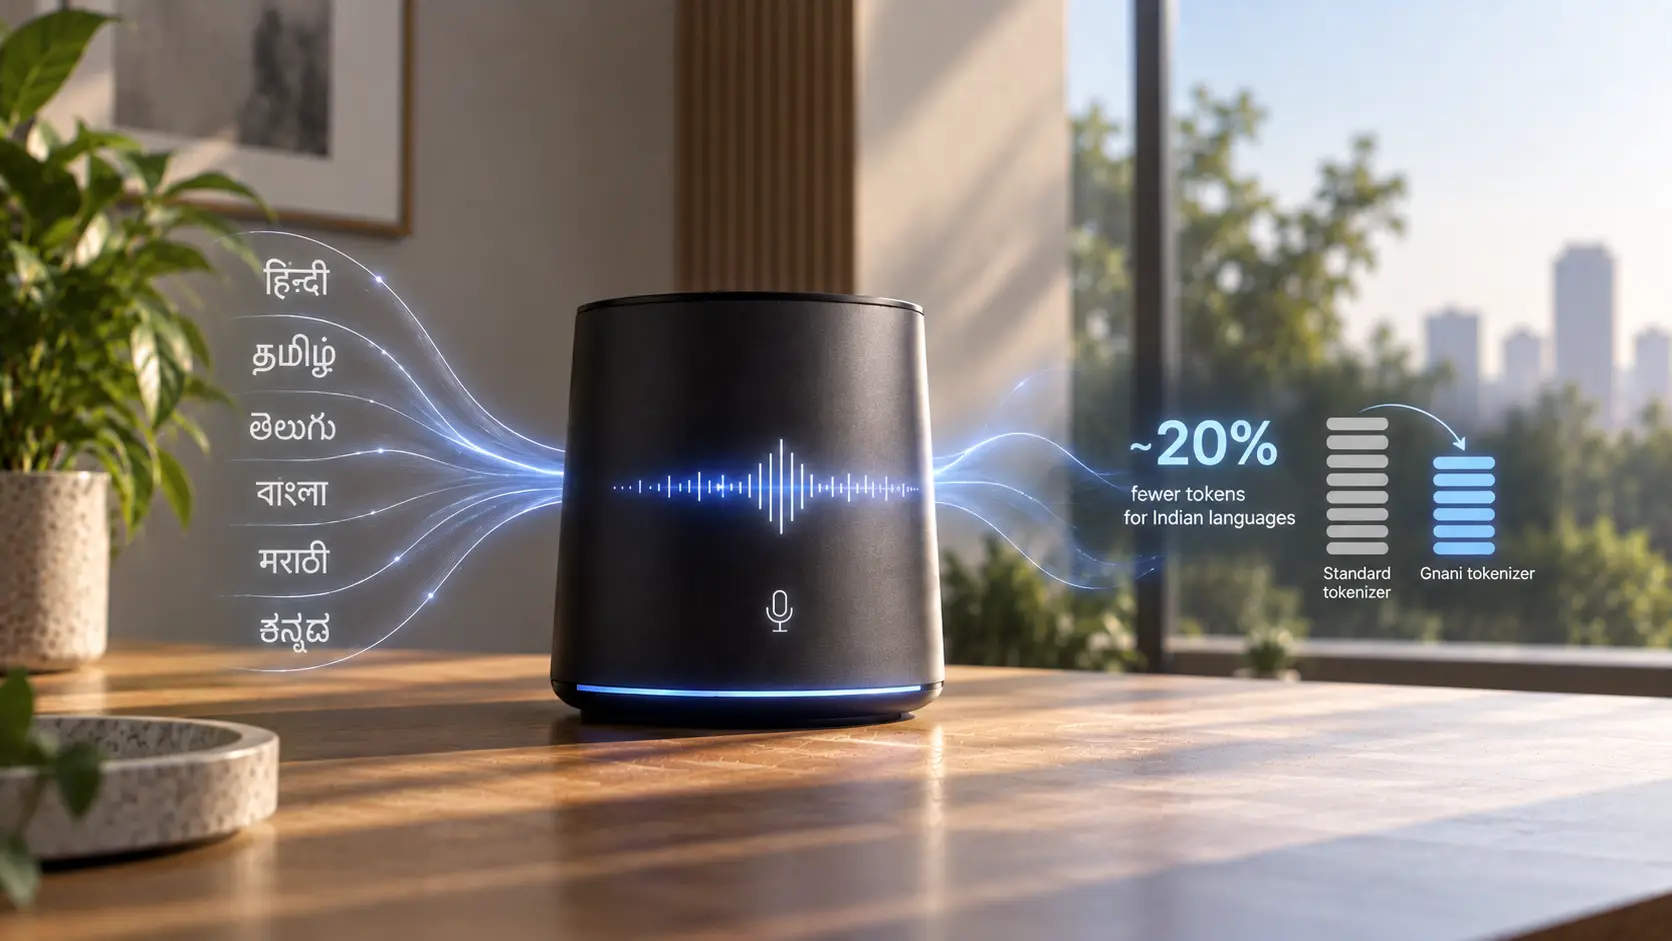
Gnani says the model was trained on more than 2 trillion tokens, essentially a very large volume of text used to teach the model language patterns, reasoning and domain knowledge. The company also rebuilt its tokeniser, the system that breaks text into units an AI model can process, specifically for Indian scripts. Gnani says this reduces the number of tokens required per Indian-language word by about 20% compared with the GPT-5 family tokeniser, which can translate into faster processing and lower inference costs.
Those performance claims still need independent validation. In Gnani’s testing, Evon 3.3 scored above Sarvam-105B on the MILU benchmark in 10 of the 11 languages evaluated, but the results come from the company’s internal testing.
Why Does It Matter?
The important part of Artha may be less about whether a 30-billion-parameter model can outperform a larger one and more about what organisations can do with it.
Artha is designed for deployment inside an organisation’s own infrastructure. Evon’s weights are available under an Apache 2.0 licence, allowing organisations to adapt the model and deploy derivatives in their own data centres or virtual private clouds. That can be particularly relevant for banks, insurers and government departments that work with sensitive or regulated information.
Ganesh Gopalan, Gnani AI’s co-founder and CEO, described the principle more directly in an interaction with Indian Express: “Sovereign AI is not about keeping the world out.” He argued that it is about India having the capability to build for itself and then for other countries facing similar problems.
This is where smaller and specialised models also become relevant. Large frontier models maximise general capability, but specialised models can be more practical where workloads are narrow, languages are local, and latency, privacy or inference cost matter. The question is therefore not whether smaller models should replace larger ones, but whether India’s AI ecosystem needs both.
What Happens Next?
The first test will be independent benchmarking.
Gnani’s claims around Indian-language performance, token efficiency and inference cost need to be validated outside the company. Real-world deployments will also show whether Evon’s language optimisation translates into lower operating costs and better performance across critical sectors such as banking, insurance and government services.
The second test will be adoption. Gnani is one of “12 organisations and consortia selected under the IndiaAI Mission to develop indigenous foundational models and large or small language models based on Indian datasets.” The government says the programme is intended to build sovereign capability while addressing Indian languages and use cases.
How these models perform in actual enterprise and public-sector deployments will matter more than their parameter counts alone.
What Should India Do?
India’s sovereign-AI strategy should therefore avoid treating model size as the primary measure of progress.
The government already recognises sovereignty as a broader stack problem. Its IndiaAI strategy includes domestic foundation models, shared compute infrastructure, datasets and application development, with more than 38,000 GPUs empanelled through private AI service providers.
A useful measure of sovereignty would include whether Indian institutions can access model weights, deploy models locally, adapt them to domestic languages and sectors, control sensitive data and run them at sustainable cost.
Artha does not settle that debate. Its performance claims still need independent verification. But its launch highlights an important distinction for India’s AI strategy, that is – “while parameter count measures scale; sovereignty may ultimately depend on control.”
***
Source Note:
This article is based on Gnani AI’s August 28, 2026 launch of Artha, the company’s public disclosures on the Evon 3.3 model and Artha platform, PIB’s updates on the IndiaAI Mission’s foundational-model programme, and reporting by The Indian Express on Gnani AI’s sovereign-AI approach. Additional context on India’s broader sovereign-AI strategy was drawn from government documents on the IndiaAI Mission.
Editorial Disclosure:
AI-assisted tools were used to help summarise and organise information from the source reports and to support language and copy-editing.